「ベンチマーク4位のモデルが、実際に使うとまったく別物だった」。AI評価サイトArtificial Analysis(AA)の総合指数をめぐり、こんな批判がRedditで話題になっています[1]。AA Indexは、各社AIモデルの総合的な性能を1つのスコアにまとめた指標です。モデル選びの参考にする人も多いだけに、信頼性への疑問は波紋を広げています。
投稿したユーザーは、AA Indexで4位のKimi 3.1 Proを、OpenRouter経由で実際に試しました[1]。OpenRouterは、複数のAIモデルをまとめて利用できるサービスです。その結果、実世界の使い方ではMiMo 2.6やDeepSeek 4.1 Flashに「遠く及ばない」と報告しています[1]。実世界のユースケースでは「非常に悪い」との評価も添えられています[1]。投稿者は「AA Indexはとても簡単にゲーム化できる」、つまり試験への対策で点を稼ぎやすいと述べています[1]。ただし投稿に具体的なスコアはなく、差がどの程度だったかは素材からは確認できません。
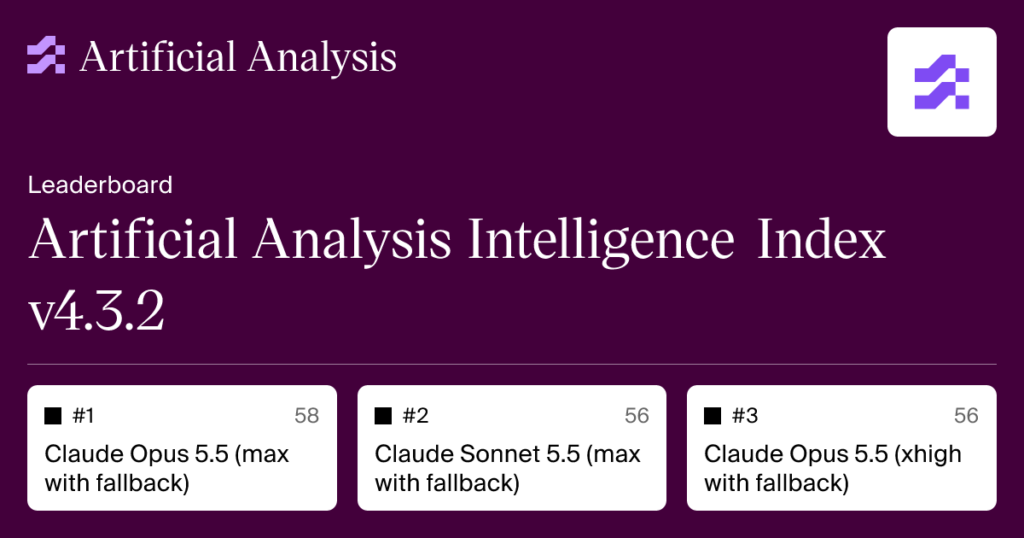
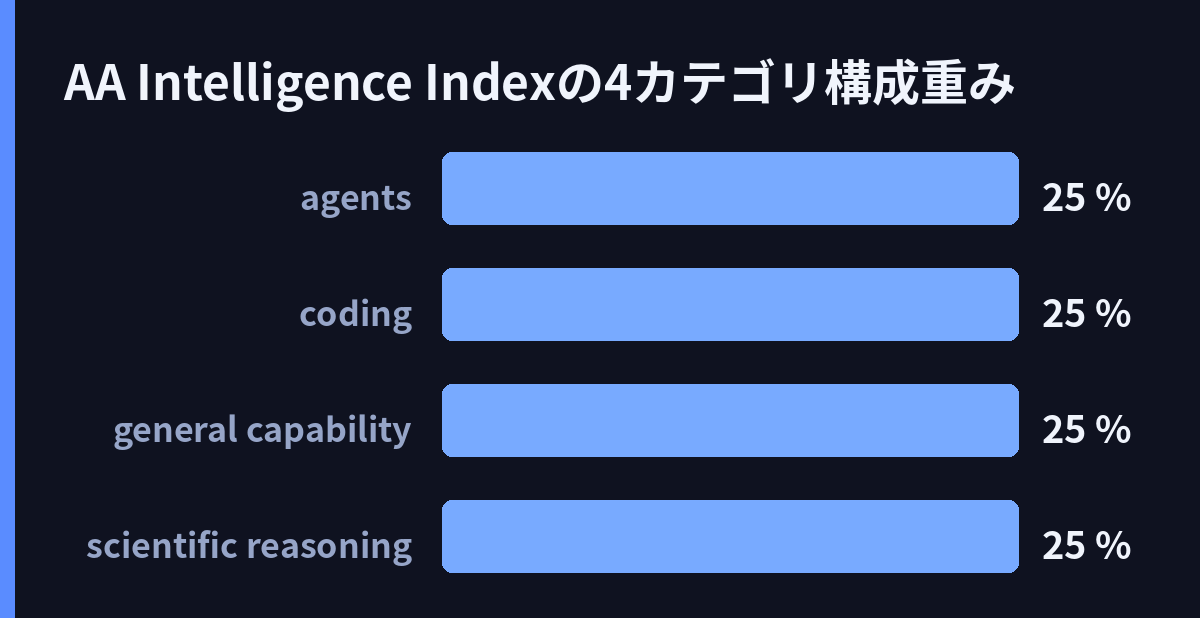
そもそもAA Indexは、どんな指標なのでしょう。現行のv4.3.2では、推論・コーディング・知識・指示追従・科学的推論・多段階タスクの成績を組み合わせ、0〜100の複合スコアにしています[2]。内訳はagents、coding、general capability、scientific reasoningの4カテゴリで、それぞれ25%ずつの重みです[2]。構成ベンチマークは10個。AA-Briefcase v1.1やGDPval-AA v2.1のほか、Terminal-Bench 4.0、SciCode、Humanity’s Last Examなどが並びます[2]。現在の首位はClaude Opus 5.5(Max, Default Fallback)、スコアは58です[2]。
個々の試験の中身を見ると、特徴がはっきりします。AA-Briefcase v1.1は、スプレッドシートやプレゼン資料、メモといった成果物を作らせる業務ワークフロー試験です[3]。GDPval-AA v2.1は44職種・9業界の実務課題を試します[3]。モデルにはシェル操作とウェブ閲覧が許され、ブラインドのペア比較からEloレーティング(対戦の勝敗から強さを数値化する手法)を算出します[3]。Harvey LAB-AA v1.1は、24の法務分野にわたる120の非公開タスクで法律業務を測ります[3]。このほか、SaaSアプリの模擬環境でタスク達成率を測るAutomationBench-AAなど、業務寄りの試験が中心です[3]。
ところが、ここに意外な但し書きがあります。AA自身が公式で、こう説明しているのです[2]。総合スコアが高いことは、全体としての性能の強さを示すものです。しかしコーディングやエージェント用途など個別の用途では、個別ベンチマークの方が参考になる、と。つまり公式も、1つの数字ですべてを判断する使い方を推奨していません。一方で、Reddit投稿も単一ユーザーの主観テストであり、検証可能な数値は示されていません[1]。批判する側とされる側の両方に、留意点がある形です。
興味深いのは、AA自身がGDPval-AAを「実世界のタスク」の試験と説明している点です[3]。実世界指向をうたう試験の集合体が、なぜ実使用とズレて見えるのか。そこが議論の分かれ目のようです。Webでも、「Artificial Analysisは有用だが、インデックスは実世界の妥当性を欠く」と題した記事[6]や、AI評価とベンチマークの課題を論じる記事[7]が現れました。Kimi K3を巡っては、ベンチマークの進化を「Pelicanテストのその先」として論じる記事[5]や、「蒸留で確保した性能という幻想」と題した記事[8]もあります。蒸留とは、大きなモデルの能力を小さなモデルに写し取る手法です。Stanford HAIの「AI Index Report 2026」も技術性能を独立した項目で扱っており、評価のあり方そのものが問われているようです。
AAはKimiモデルの一覧ページで、知能・性能・価格の比較も提供しています[4]。情報は豊富になる一方、最終的に頼れるのは、自分の用途に近い試験の結果です。コーディングならTerminal-Bench 4.0、実務課題ならGDPval-AA v2.1のように、個別ベンチマークを確認するのが実用的です[2]。総合指数は全体の目安と割り切り、実際に使った人の報告と組み合わせて読むこと。今回の騒動は、それを改めて思い出させてくれました。
引用ソース
- Reddit Reddit r/LocalLLaMA: Artificial Analysis Index is non-representative of real-world performance. Tested Kimi 3.1 Pro through OpenRouter, the number 4 model in AAI, it’s not even close to MiMo 2.6 or DeepSeek 4.1 Flash — https://www.reddit.com/r/LocalLLaMA/comments/1xercio/artificial_analysis_index_is_nonrepresentative_of/
Artificial Analysis Index is non-representative of real-world performance. Tested Kimi 3.1 Pro through OpenRouter, the number 4 model in AAI, it’s not even close to MiMo 2.6 or DeepSeek 4.1 Flash
- Web記事 記事全文: Artificial Analysis Intelligence Index v4.3.2 — https://artificialanalysis.ai/evaluations/artificial-analysis-intelligence-index
Artificial Analysis Intelligence Index v4.3.2
Artificial Analysis Intelligence Index
Score
Artificial Analysis Intelligence Index: Score
Intelligence Index vs. Cost per Task
Token Usage
Artificial Analysis Intelligence I - Web記事 記事全文: AI Model Evaluations – Artificial Analysis — https://artificialanalysis.ai/evaluations
Artificial Analysis Intelligence Index v4.3.2
A composite benchmark aggregating ten challenging evaluations to provide a holistic measure of AI capabilities across mathematics, science, coding, and reasoning.
AA-Briefcas - Web記事 Web検索: Kimi Models – Intelligence, Performance & Price Comparison | Artificial … — https://artificialanalysis.ai/models/creators/kimi
Kimi Models – Intelligence, Performance & Price Comparison | Artificial …
- Web記事 Web検索: Kimi K3 and the Evolution of AI Model Benchmarking: Beyond the Pelican … — https://techplanet.today/post/kimi-k3-and-the-evolution-of-ai-model-benchmarking-beyond-the-pelican-test
Kimi K3 and the Evolution of AI Model Benchmarking: Beyond the Pelican …
- Web記事 Web検索: Artificial Analysis useful but index lacks real-world validity – AI … — https://artificialintelligencedynamics.com/2026/06/17/artificial-analysis-useful-but-index-lacks-real-world-validity/
Artificial Analysis useful but index lacks real-world validity – AI …
- Web記事 Web検索: AI Evaluation and Benchmarking Challenges: Bridging the Gap Between … — https://qznc.github.io/md_news/ai/2026/07/20.html
AI Evaluation and Benchmarking Challenges: Bridging the Gap Between …
- Web記事 Web検索: “The Illusion of Performance Secured Through Distillation”: Kimi K3 … — https://economy.ac/news/2026/07/202607289627
“The Illusion of Performance Secured Through Distillation”: Kimi K3 …
※ 本記事はAIにより、Reddit・Hacker News・5ch・Xトレンドの公開投稿・トレンドを軸に、その話題をWeb検索で深掘りして集めた一次情報(記事全文・HNコメント)を併せて自動生成されました。本文中の[n]は末尾の引用ソース番号です。内容の正確性は保証されません。引用先を必ずご確認ください。
RECENT COMMENTS